Haddrell from Scratch
Building this site with agentic tools — what was decided, in the order it happened.
I have read other people’s engineering blogs for years, and I have considered writing one of my own for about as long as I can remember. The pattern was always the same: I would skim a well-argued post over coffee, mentally catalogue three things I had been meaning to write about, and then close the tab and get on with the day.
The reason it never happened was opportunity cost. Producing a blog I would be proud of meant real effort, and that effort was always better spent on the problems my clients and employers were paying me to solve. So it stayed an idea — not a stalled project, because I never started.
Two things changed together. The first is that the cost of producing a blog at the quality I wanted has dropped radically — a few evenings to set it up, and content in under an hour when the mood takes me. The second is that software itself has shifted, and I wanted a way to signal I am on board with the newer toolset and working style in a way that is not obvious from my work history. Hence the blog.
What follows is the build itself, in the order it happened — several evenings of focused work, spread across a week.
The working pattern was familiar: brainstorm where it helped, let the agent write a plan I could read and critique, iterate on the plan, then have the agent execute with me reviewing each move. Not every change needed every stage. What these tools really change is the cost of iterating — reopening a decision or pivoting mid-build is a few minutes of work, not a rewrite.
1. Plan first, code second.
Before any code, a brainstorm. I explained what I had — a domain, a family email setup I was not going to disturb, a vague desire to write — and what I wanted. The agent asked clarifying questions; a design came out of that. We walked through the technical detail, researched specific choices where I was not sure, iterated, and improved.
Only then did the plan get written: PLAN.md, covering scope, stack,
content model, and deployment; and CONTEXT.md, covering the fixed
constraints around email, DNS authority, and which accounts I was
willing to move.
The first version came back longer than expected and wrong in several interesting ways. The stack section had recommended an analytics vendor I had no intention of using. The content model had quietly invented a “series” concept that did not fit how I think about write-ups. The deployment section had blithely proposed moving nameservers on a production family email domain without flagging it as a decision worth discussing. I read both files end to end, wrote a response that went through each section in order with corrections, and handed that back.
The second pass was narrower, more honest about trade-offs, and flagged the nameserver question as explicitly not-yet-decided. Only after that did the agent get to write code.
The receipt: the build had not yet begun. That was the discipline — paying for the plan in brainstorm and critique before paying for it in code.
2. Identity & voice.
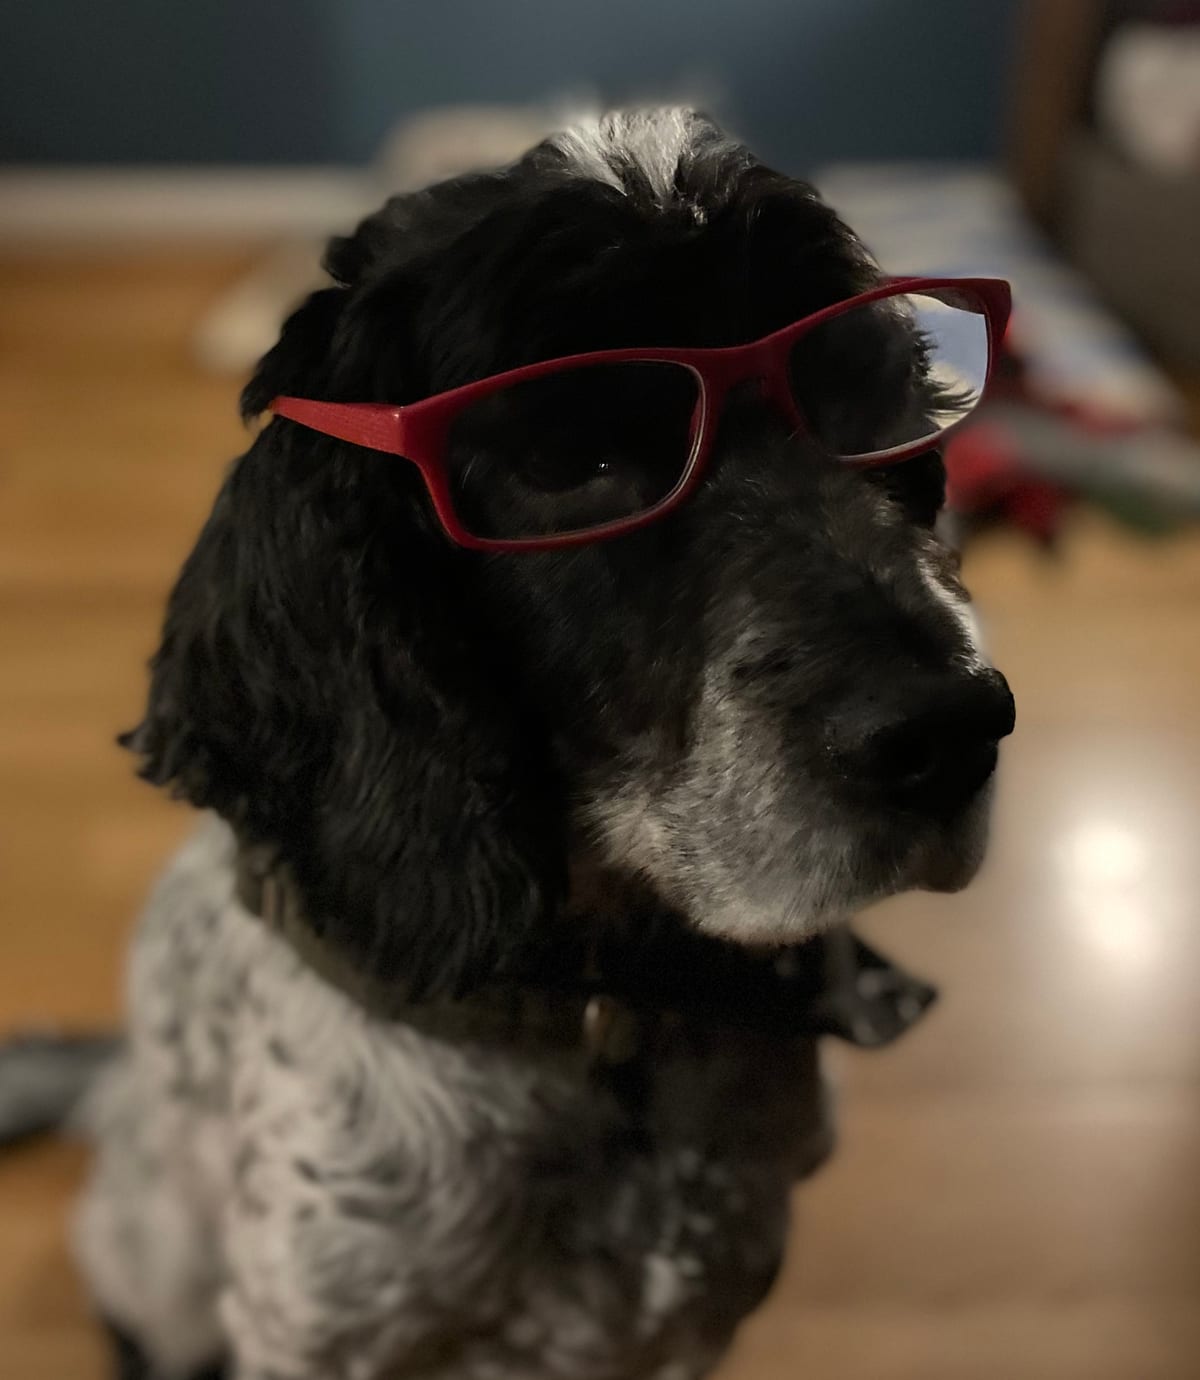
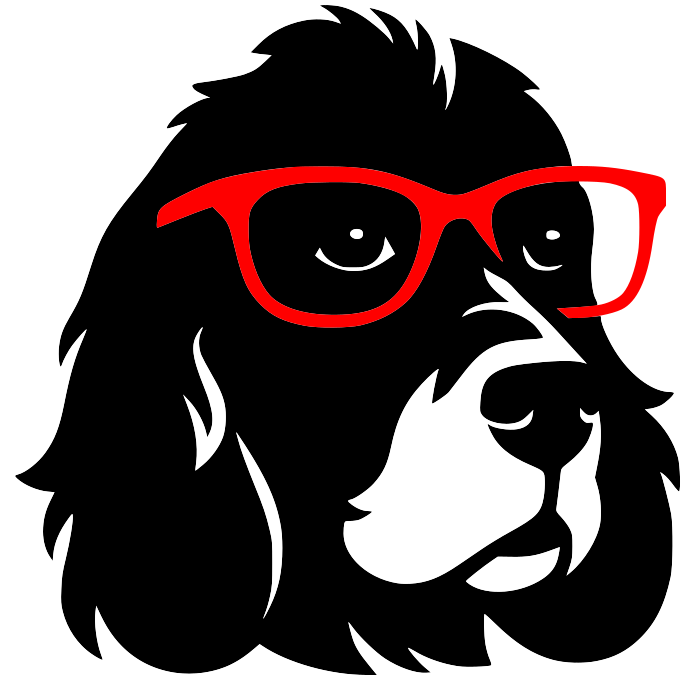
The favicon is Dougal: an abstracted three-colour geometric figure (one red, one black, one off-white) built from a photograph of a black and grey dog wearing round red-rimmed glasses. My dog, Dougal, the family Cocker Spaniel. The abstraction kept the glasses and the colour triad and threw away the rest. Everything else on the site was picked to sit with it.
The body typeface is IBM Plex Sans, with IBM Plex Mono for inline code —
named, recognisable, not the system stack that most post-scaffolding
templates fall back to. The palette is editorial rather than
product-marketing: a specific accent red picked from the mark, hairlines
instead of soft shadows, no gradients. The layout is deliberately
asymmetric on wider screens. Dates render in the human UK format,
e.g. 15 Apr 2026, not the ISO 2026-04-15 that creeps into templates
written by software.
None of those individually proves anything. The point is the cumulative effect: a set of small decisions that, taken together, do not look like a post-scaffolding default. The receipt is the cover of the site itself — every choice made by a human, even when the typing was shared with an agent.
3. Content model.
Two collections, no more. Essays are the long, argued pieces; builds are
the project write-ups numbered for continuity — this is 001. Builds are
personal projects only. Client work, by long-standing habit and contract,
never appears here; the interesting parts of that work are not mine to
tell.
Tags cut across both collections rather than being scoped to one. That
came out of asking which axis was going to be most useful to a reader
three posts in, and the answer was topic rather than container — an
astro tag that applies to both an essay about static-site thinking and a
build that uses Astro is more useful than the same information duplicated
per collection.
What is deliberately missing: comments, a newsletter, any published
cadence. I was not going to maintain a comments queue. I was not going to
promise a post a month and miss. The content collection schema in
src/content.config.ts sets the fields each post must carry — title,
description, pubDate, tags, draft — and the build enforces them at
compile time.
The receipt: schema first, scope bounded by what I would actually keep up to.
4. Agent-readability as a first-class concern.
Readers of this post include people and software. Both were designed for from the start, not bolted on afterwards.
The specifics: llms.txt at the root, declaring the site’s intent and
pointing at llms-full.txt, which carries the machine-legible copy of
every post concatenated into one file. A .md companion alongside every
HTML page, served as the canonical text under a URL that drops the Astro
rendering entirely. JSON-LD BlogPosting metadata on every detail page.
Pagefind for client-side search, so the search index is bundled with the
build and needs no server. The RSS feed carries full post content rather
than excerpts, because the point of RSS is readable text, not a teaser
with a link.
None of this is new. The llms.txt convention is recent and structured
metadata is not, but they were both in scope from the start and treated
as part of the shape of a post, not as SEO busywork. Pagefind replaced an
earlier plan for a client-side Lunr index because it was a better fit for
the static-build story.
The receipt: the site exposes the same text to a reader and to their tools, and does it from the templates rather than from a retrofit.
5. Deployment, and a plan reversal.
Cloudflare Pages was the deployment target from the start. The Workers runtime was well understood, the deploy was a two-command pipeline, and the edge-cached static output was a sensible fit for something that serves a couple of kilobytes of text per page.
DNS was where the plan changed.
The original PLAN.md was cautious. The domain had been on GoDaddy for
years and was wired into Microsoft Domain Connect for a family M365
mailbox. Changing nameservers meant migrating every existing record — MX,
Autodiscover, SPF, and the ones Domain Connect manages automatically — by
hand. The plan said do not touch that. Put the site at a subdomain
instead.
At deployment, I reconsidered. The disadvantages of staying on GoDaddy — slower TTLs, duplicate management UIs, no Cloudflare edge features — outweighed the risk of moving the zone, provided the move was reversible. I captured the existing GoDaddy nameservers verbatim in a note before touching anything, exported every record from the old zone, and then pointed the domain at Cloudflare. Email kept working.
The receipt: the plan changed mid-flight, and the reversal was written down. The most honest moment of the build — not a pivot sold as a feature, a decision reopened because the original reason did not survive contact with reality.
6. Post-launch hardening.
Shipping the site was not the same as finishing it. Once the main pages were up, a second set of commits landed to make the site behave like something somebody actually maintains.
The social sharing surface went in first: an Open Graph image, a coherent
set of <meta> tags, card variants for services that want them, absolute
URLs where they mattered. Paste any page into Slack or Messages and the
preview fills in. A GitHub icon moved into the site header, because
sending a reader from a build write-up to the repo it is describing is
the point.
The repository then picked up a code-review pass driven by a separate
agent session, whose job was to find what the first pass missed — small
defects, unused exports, inconsistent error handling. Then a GitHub
Actions workflow: build on every PR and every push to main, with
npm run lint and npm run check as required steps. The build itself
catches markdown schema errors at compile time; the lint step catches
everything else.
Finally, dependency hygiene. Dependabot was enabled for weekly PRs. The
yaml transitive dropped into the tree by astro-pagefind was pinned to
a fixed version to address an advisory flagged against the range.
The receipt: the unsexy work after “it’s live”. It does not look like anything, which is the point.
7. Gaps.
Two things stand out as rough edges when I read the finished site back.
The Open Graph image is shared across every page rather than generated per post. That is fine for the launch — a consistent thumbnail is better than an inconsistent one — but build cards would read better with their own.
There is no link checker in the CI pipeline. For a static blog with no unit tests, stale links are the realistic failure mode as posts accumulate, and catching them at build time is a one-GitHub-Action exercise.
The repo for this site is public at
github.com/Jodre11/haddrell-blog
— the commits tell the same story at a different zoom level. Future
builds will appear here as 002-…, 003-…, and so on.